Which data can you enter in which AI tool?
- AI literacy
- AI privacy
- Personal data in AI tools
- Copilot and GDPR
- AI chatbot data breach
In August 2024, the Dutch Data Protection Authority (Autoriteit Persoonsgegevens, AP) reported that it was receiving data breach notifications that had all happened the same way: an employee pasted personal data into an AI chatbot. At a GP practice, an employee entered patients’ medical data, against the agreed rules. At a telecoms company, a file of customer addresses ended up in a chatbot. Neither of them meant any harm. They wanted to work faster, and the tool was open in their browser. The same situation plays out in many more places: the law firm that has a court filing summarised, the municipality that has an objection letter sorted, the care provider that has a report rewritten. So the question is not whether you may use AI, but which data you put into which tool. The answer depends on three things: the tool, the account you are logged in with and the agreements your organisation has made with the supplier.
What exactly does the Dutch regulator say?
In its warning, the AP draws a distinction that often gets lost in practice. If an employee uses a chatbot on their own initiative and enters personal data, that is a data breach. In many cases the organisation must report it to the regulator and to the people concerned. If the organisation has included the chatbot in its own policy, it is not a data breach, but according to the AP it is often still not allowed. Writing a policy is not enough: the policy also has to comply with the GDPR. The AP is a Dutch regulator, but the GDPR rule behind its warning applies in every EU member state, so the same reasoning holds in Belgium, Luxembourg and beyond.
The AP gives the reason straight away. Most chatbot providers store everything you enter. Your data then sits on their servers, often without the person who entered it realising, and the person it is about knows nothing at all. The AP therefore asks organisations for two things: agree with employees which data they may and may not enter, and arrange with the provider that it does not store the data entered.
The account counts, not the name of the tool
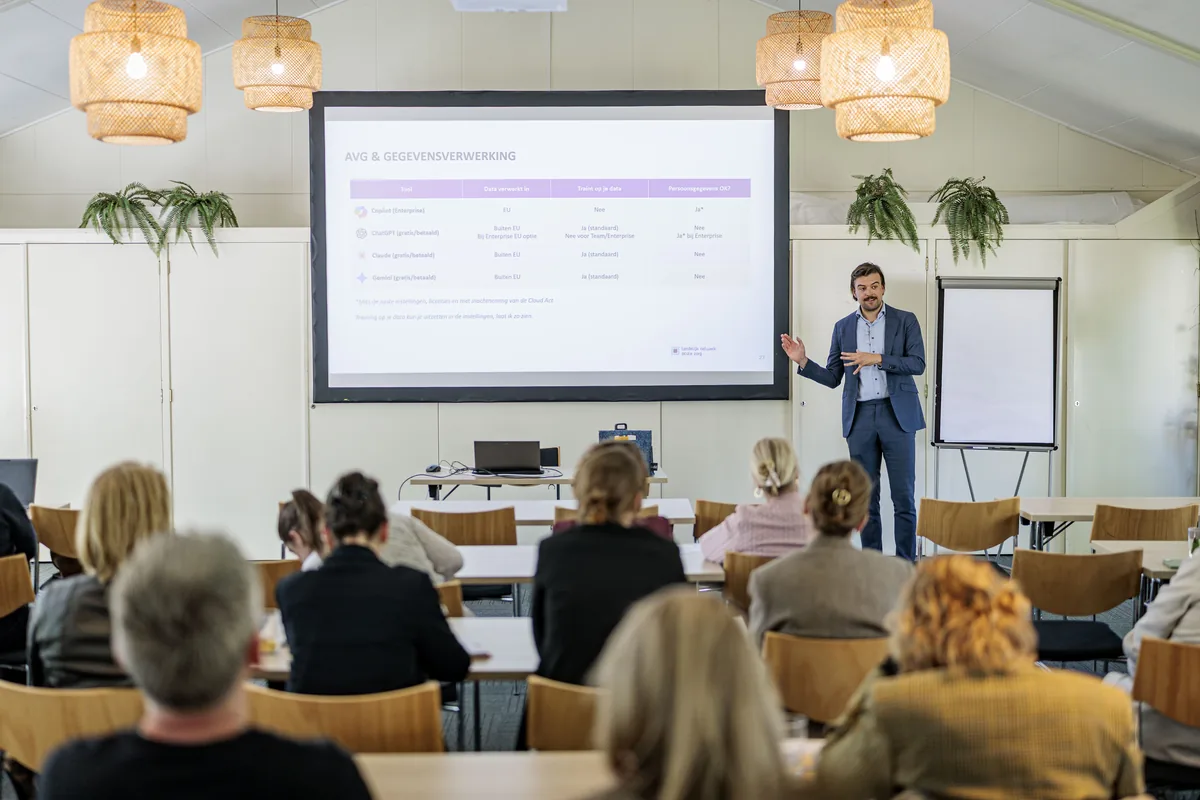
Copilot, ChatGPT, Claude and Gemini all come in a free version, a paid personal version and a business version that an organisation buys. On screen they look the same, but what happens to your data differs greatly. With a free or personal account, your organisation has no agreement with the supplier. There is no data processing agreement, you do not know where the data is stored, and with some services what you enter can be used to train the model further. Personal data and confidential documents do not belong there.
A business environment is different. Take Microsoft Copilot within Microsoft 365. In its documentation on enterprise data protection, Microsoft describes how it then acts as a processor, under the same terms that apply to your mail in Exchange and your files in SharePoint. Prompts and responses are not used to train the underlying models, and Copilot follows the permissions and sensitivity labels your organisation has set. The same documentation contains two caveats. Web searches that Copilot runs through Bing fall outside those terms. And for the Anthropic models you can choose in Copilot, the EU Data Boundary does not currently apply. A business licence is a good foundation, then, but not a free pass: someone in your organisation has to work out and record what is and is not allowed.
What has your profession already set down?
You do not have to work all of this out yourself, because many professions already have a framework. The Netherlands Bar (Nederlandse Orde van Advocaten, NOvA) writes in its recommendations on AI in the legal profession that lawyers should not enter confidential or client data into public AI models and should not use confidential data in free tools. The lower the price, the greater the chance that the supplier does something with your data, according to the Bar. So read the terms yourself and do not rely on the supplier’s marketing. Bar associations in other EU countries are reaching similar conclusions, so check what yours says.
For government, the Dutch cabinet, together with municipalities, provinces and water authorities, set down a government-wide position on generative AI in April 2025. It gives civil servants more room to use generative AI, for example to answer residents’ questions faster, provided there is a risk analysis and employees are AI literate. In healthcare, medical confidentiality is the starting point, and the GP practice’s breach notification shows how quickly things go wrong without clear agreements. On top of that, since 2 February 2025 the EU AI Act has required organisations across the EU to ensure sufficient AI literacy among everyone who works with AI on their behalf (Article 4). Knowing which data may go into which tool is self-evidently part of that.
What stays the same, and what changes?
Much of what you already know still applies. Professional secrecy, the GDPR and confidentiality agreements with clients do not change because there is an AI tool in between. You ask whether this information may go to this party when you use an external translator, a transcription agency or a cloud service as well. In that respect an AI tool is a new recipient of your data, and you make the same assessment as with any other recipient.
What does change is the ease and the scale. Uploading an entire case file takes two clicks. A copied email thread quickly contains names, phone numbers and details you did not think about. And more and more assistants are connected to your mailbox, your shared folders or your case management system. Such an assistant can use everything you have access to, including the folder that was once accidentally opened up to the whole department. So think ahead, not only about what you enter yourself, but also about what the tool can retrieve on its own.
A traffic light for each type of data
A format that works well in practice is a traffic light for each type of data. It fits on one A4 page and any colleague can explain it in a minute.
- Green: public or general information, such as a statutory provision, a text from your own website or a question without names. This can go into any tool, including a free version.
- Amber: internal information without personal data, such as a draft policy, a work instruction or a fully anonymised case. This can only go into the business environment your organisation has approved.
- Red: personal data, medical data, client and customer files, and anything covered by professional secrecy. This can only go into an environment explicitly set up for it, with a data processing agreement and a policy that allows it. Otherwise, no.
Under the traffic light, list which tools your organisation has approved, with which account, and who employees can go to when in doubt. Also agree what someone does if things go wrong anyway: who reports it, to whom and how quickly. Under the GDPR, you report a data breach that poses a risk to the people concerned to your national data protection authority within 72 hours. When anonymising, watch what can still be traced back. Removing a name is not enough if the text still contains an age, a place of residence, a rare profession or an unusual condition. Replace such details with general terms, such as a middle-aged patient or a municipality in the province of Gelderland, before a document can be called amber.
How to start this week
First check which account you are logged in with in the AI tool of your choice: personal or work, free or paid. Then ask your IT department or your data protection officer which tools are approved and what agreements are in place with the supplier. Next, take a document you use often, remove the names and traceable details, and carry out the task with that version. You will quickly notice that for most tasks, such as structuring, rewriting or making a first draft, you do not need the personal data at all.
Would you like to practise this with your team on your own work, with your organisation’s tools and policy? We do exactly that in the hands-on AI literacy training and in our training for the legal profession and the public sector.
Frequently asked questions
Is it a data breach if I enter personal data into ChatGPT?
According to the Dutch regulator, yes, if you do so on your own initiative and against your employer’s rules. In many cases your organisation must then report the breach to the data protection authority and to the people concerned. Because the rule comes from the GDPR, the same applies elsewhere in the EU.
May I enter patient data into Microsoft Copilot?
Only if your organisation has set Copilot up for business use, has the data processing agreement and permissions in order, and its policy explicitly allows medical data to be processed in it. If any of those three is missing, no.
Is anonymising enough?
Only if the text genuinely can no longer be traced back to a person. Removing a name is often not enough: an age, a place of residence, a profession or a rare condition can also make someone recognisable.